GPT-X3-150M
Try GPT-X3
GPT-X3 is a base model, not a chatbot: type the start of a passage and it continues the text. It runs entirely in your browser. The first run downloads a 267 MB model file.
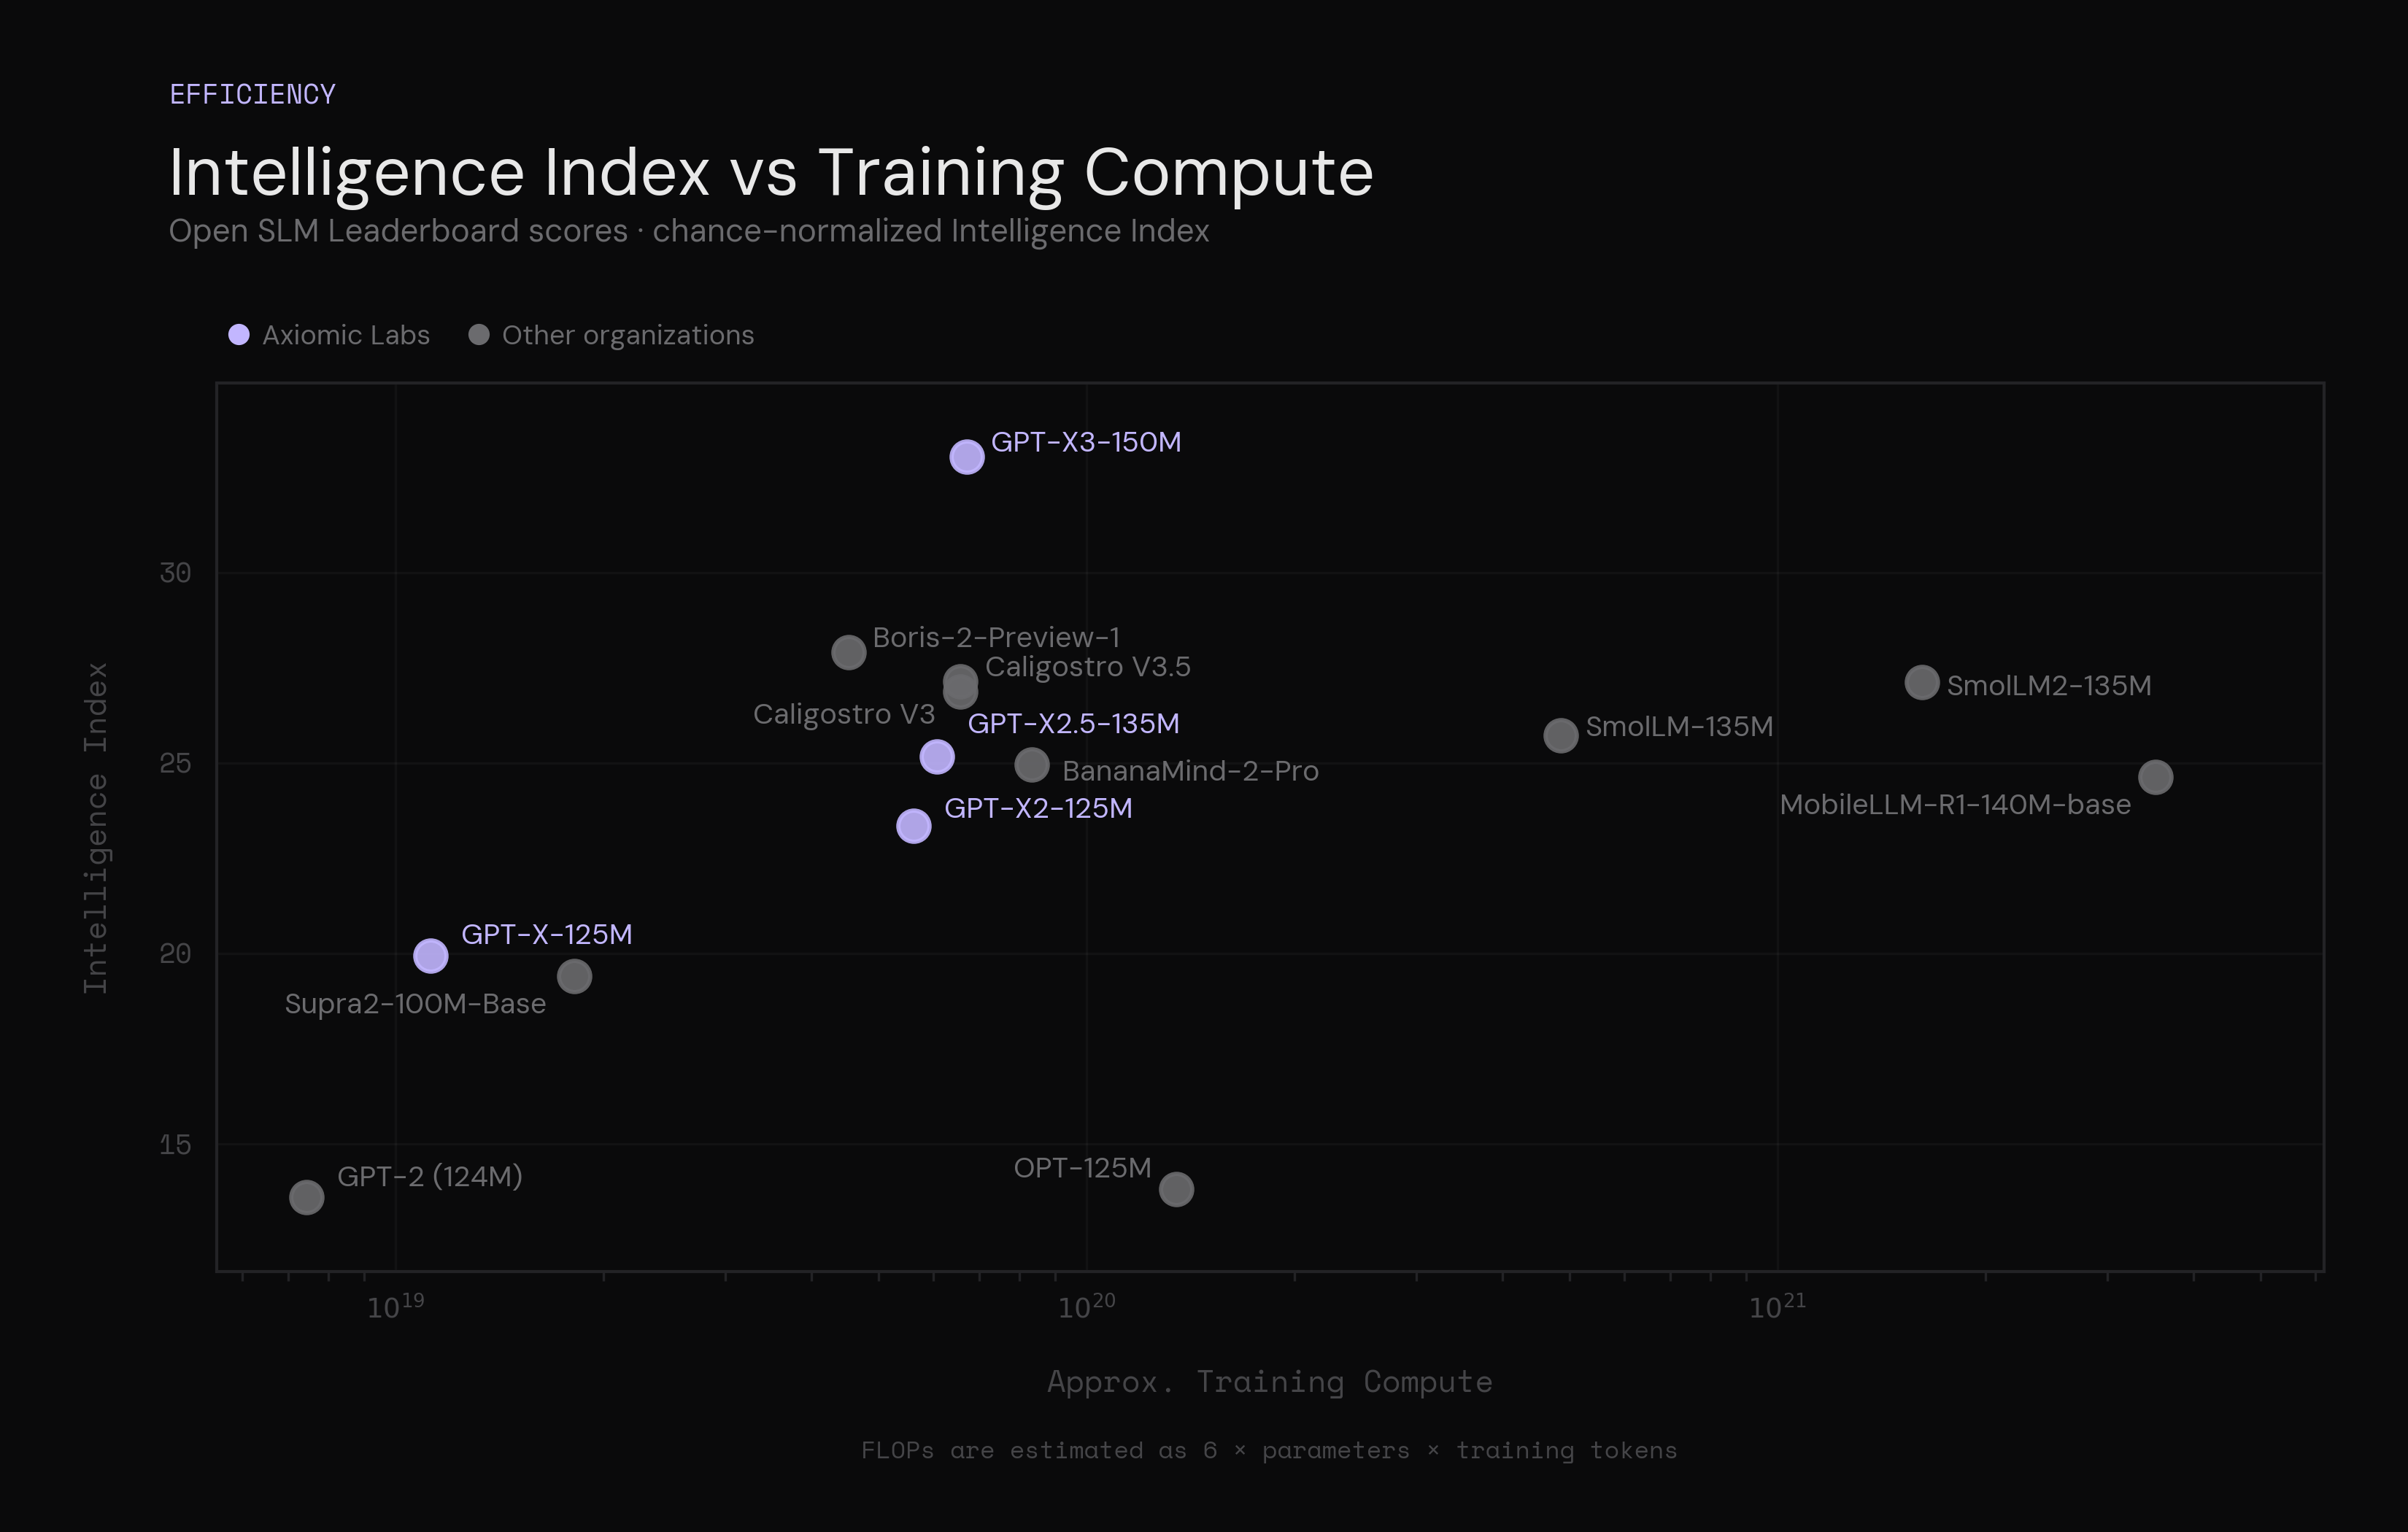
GPT-X3 is the best small language model in the world*. It ranks first on the Open SLM Leaderboard with an Intelligence Index of 33.05, the first score above 30 from a model under 150M parameters.
It also beats LiquidAI's LFM2.5-350M and Google's Gemma-3-270M, which have more than twice as many parameters. The weights are on Hugging Face under the Apache 2.0 licence.
Specifications
| Parameters | 149.4 million |
|---|---|
| Architecture | TX5: 24 layers, 18 GDN2 and 6 gated GQA |
| Vocabulary | 65,536 tokens (LFM2.5 tokenizer) |
| Context length | 2,048 tokens |
| Training data | 75 billion tokens |
| Hardware | 2× RTX 3080 Ti, about 330 hours |
Performance
The top six models on the Open SLM Leaderboard, ranked by Intelligence Index.
| Model | Params | Index | HellaSwag | ARC-Easy | PIQA |
|---|---|---|---|---|---|
| GPT-X3-150M | 149M | 33.05 | 46.16% | 59.64% | 71.33% |
| LFM2.5-350M-Base | 355M | 30.50 | 44.98% | 68.86% | 67.68% |
| Boris-2-Preview-1 | 144M | 27.91 | 45.23% | 58.38% | 69.21% |
| cagliostro-v3.5 | 146M | 27.49 | 43.41% | 53.75% | 68.06% |
| SmolLM2-135M | 135M | 27.13 | 43.22% | 58.63% | 68.44% |
| Gemma-3-270M | 268M | 25.16 | 41.33% | 57.11% | 68.66% |
Changes from GPT-X2.5
- The 30 full-attention layers are replaced by 24 hybrid layers: three GDN2 layers for every gated grouped-query attention layer.
- The vocabulary doubles from 32,770 to 65,536 tokens, using the LFM2.5 tokenizer. This improves speed, training efficiency and long-context performance.
- For the first 30% of training, the model predicts groups of six tokens at once (Token-Superposition Training), then switches to ordinary next-token prediction.
- Matrix weights are optimised with Muon and all other parameters with AdamW, replacing AdamW alone.
Usage
GPT-X3-150M is a base model for text completion: give it the start of a passage and it continues the text.
from transformers import AutoModelForCausalLM, AutoTokenizer

model_id = "AxiomicLabs/GPT-X3-150M"
tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained(model_id, trust_remote_code=True)
Full training details are on the model card.
* According to a weighted average of chance-normalised scores on HellaSwag, ARC (Easy and Challenge combined), PIQA and ArithMark-3, weighted 1, 1, 1 and 0.65 respectively. This is the Intelligence Index used by the Open SLM Leaderboard.